MoE Routing Collapse Still Happens Silently - Most Tools (Including MoEWatch v0.1) Only Detect It After the Run Is Already Wasted 
MoE models fail quietly as experts gradually die, routing entropy steadily collapses, and a single expert ends up taking most of the tokens, leaving you to discover the damage only after the entire training run has already been wasted.
moewatch-dev: Detect, Attribute, and Experiment on Routing Collapse While Training Is Still Running
moewatch-dev is a research and monitoring platform built for live detection, attribution, and intervention research on routing collapse in Mixture-of-Experts training.
It focuses on:
- Live detection of
expert collapseand routing failure Attributionof whichlayers / expertsare failing and why- Controlled experiments on
interventions - Benchmarking
diagnosticmethods duringtraining
Current status: Benchmarking & Experimentation
︎
 Open for research use.
This is the experimental branch (v0.2.0 under active development). APIs and features may still change.
Repo: GitHub - Abineshabee/moewatch-dev: Under Development · GitHub
Current limitations:
- Still experimental (
v0.2under active development) - Intervention strength and timing are research parameters —
not production defaults - Detection quality
depends on correctly identifying router modules - Some
custom architecturesstill requiremanual configuration - Results are sensitive to
model,data order, andcollapse pressure - It can reduce
collapse under controlled conditions; it doesnot guarantee prevention in every setting
Results: Same Run, With vs Without Live Intervention
The figures below show the difference side-by-side across router entropy, collapse risk, dead-expert counts, token-share distributions, and cumulative collapse burden.
TinyMoE model - Click and see the Benchmark results
TinyMoE is a small mixture-of-experts model used to study how a compact model’s router distributes inputs among its experts during training.
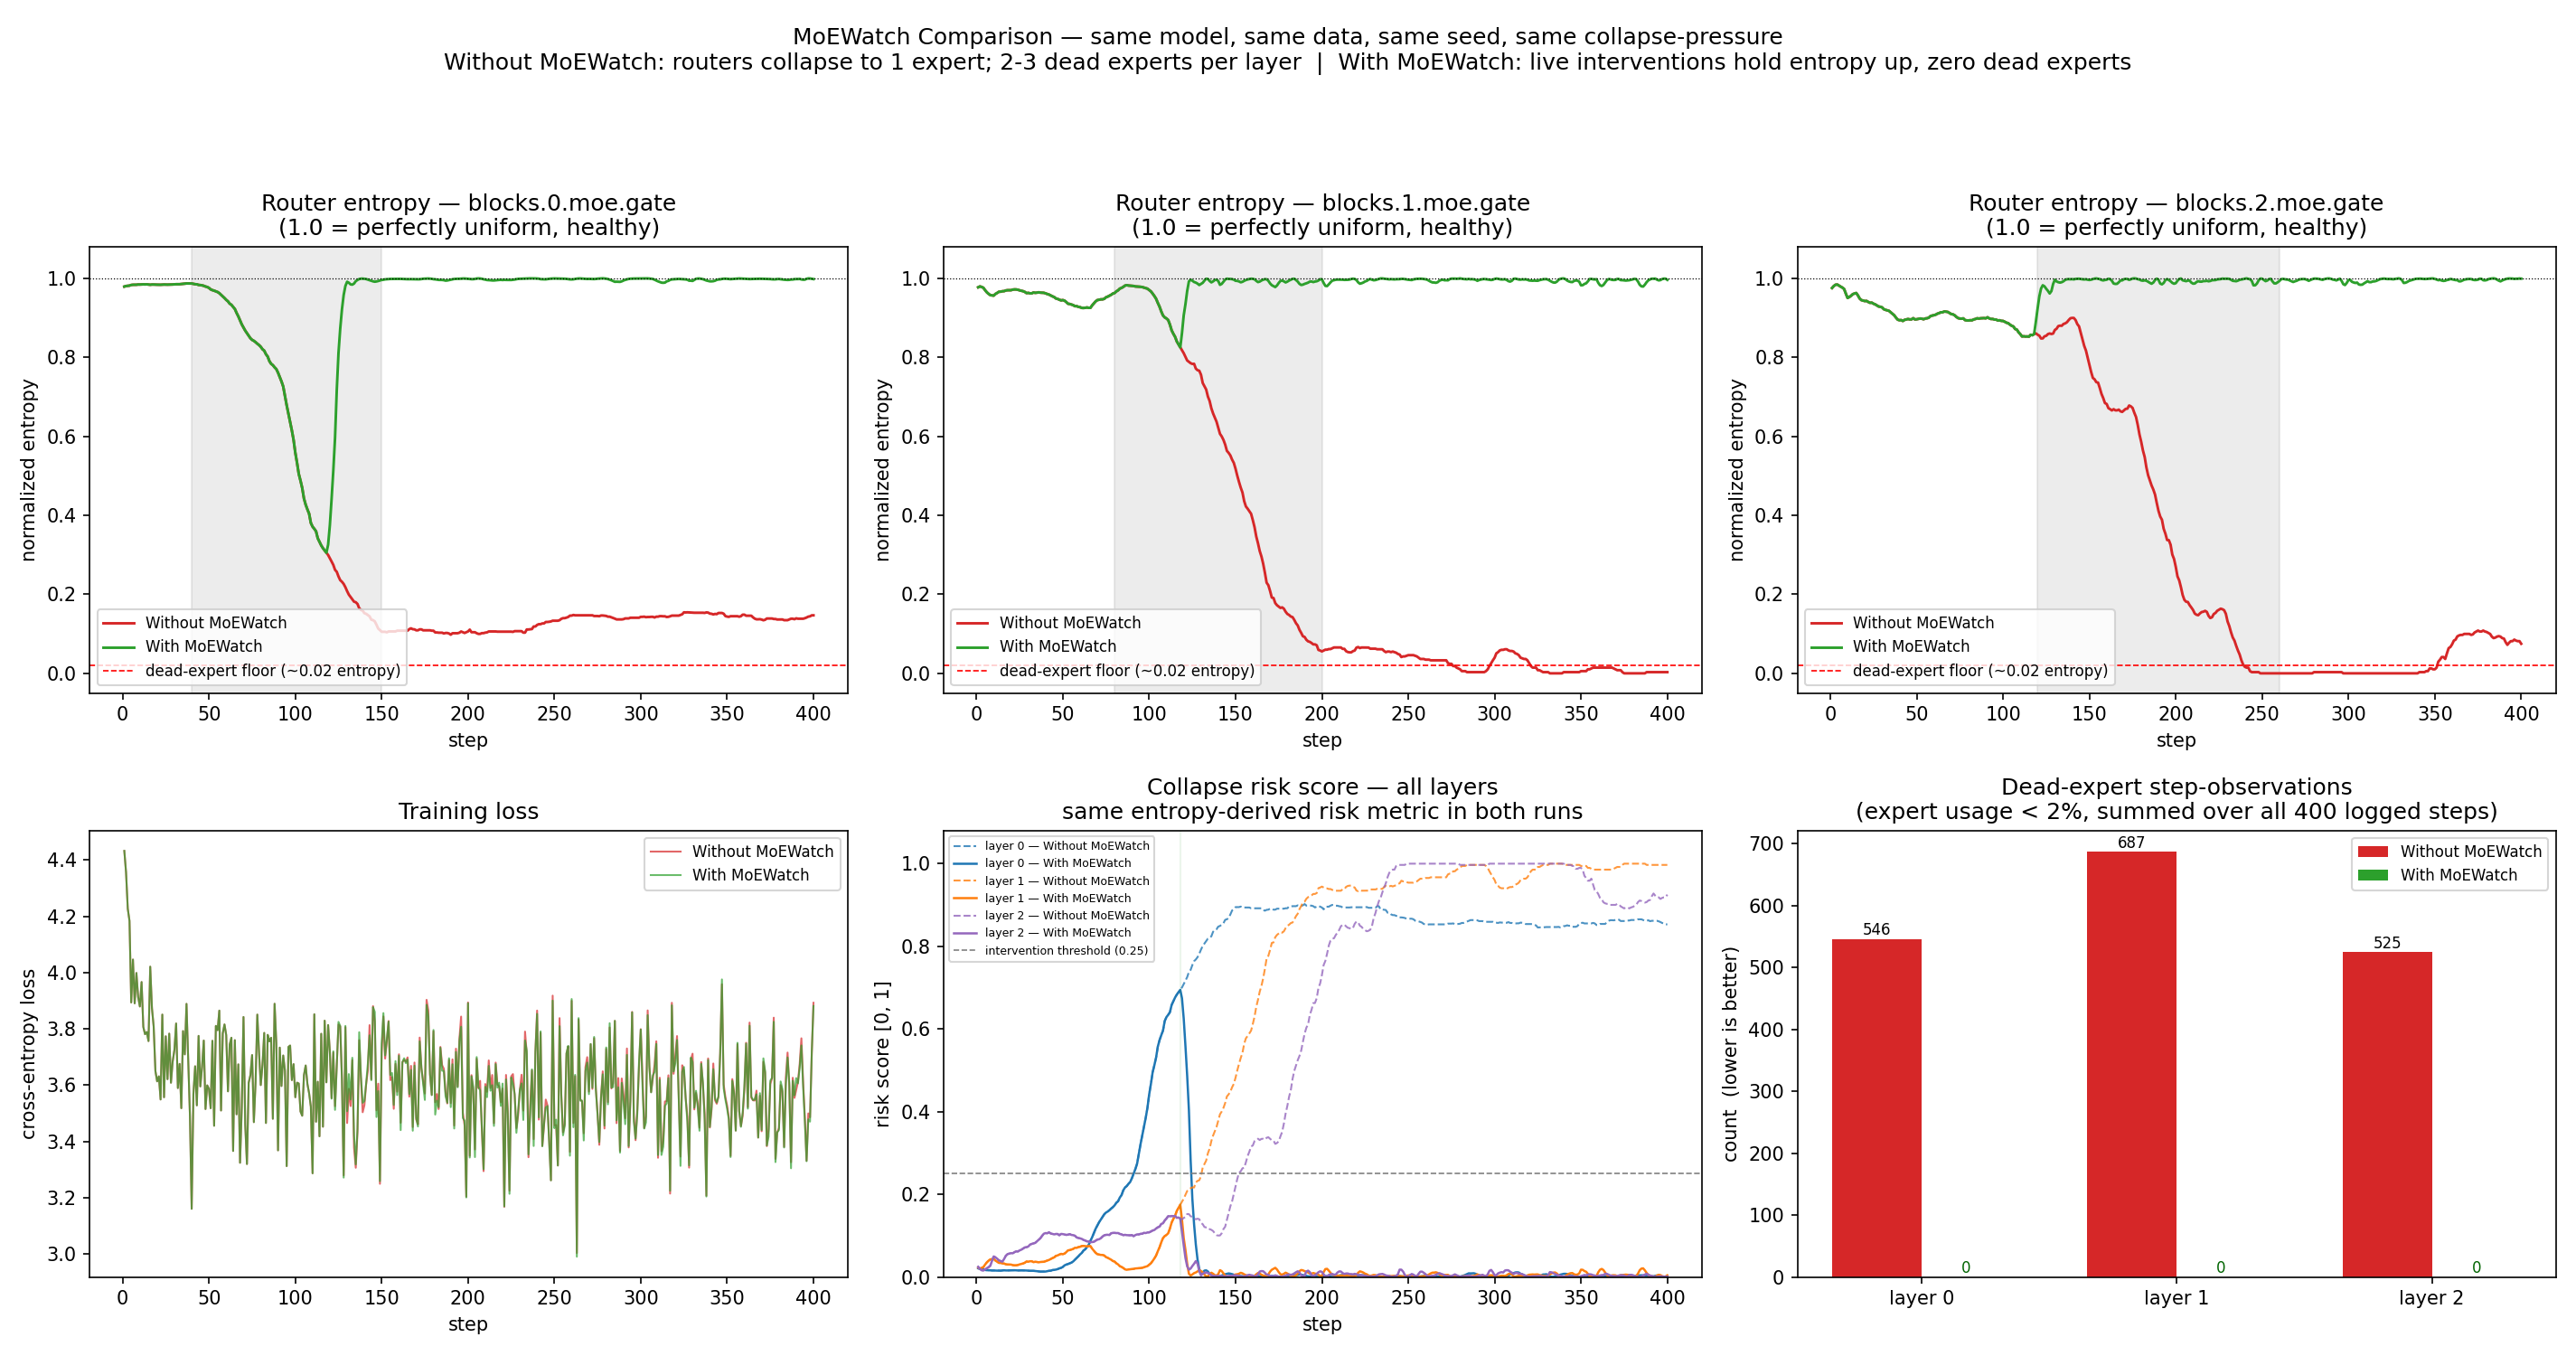
TinyMoE Results
Same model, same data, same seed, same collapse pressure.
Without MoEWatch
Routers collapse toward 1 expert2–3 dead experts appear per layerRouting entropy drops near the dead-expert floor
With MoEWatch (live interventions)
Entropy stays near healthy levelsDead experts drop to zeroCollapse risk is actively held down
Google Switch-base-8 - Click and see the Benchmark results
Google Switch-base-8 is a Switch Transformer model with eight experts, used to examine expert routing and specialization in a larger-scale mixture-of-experts architecture.
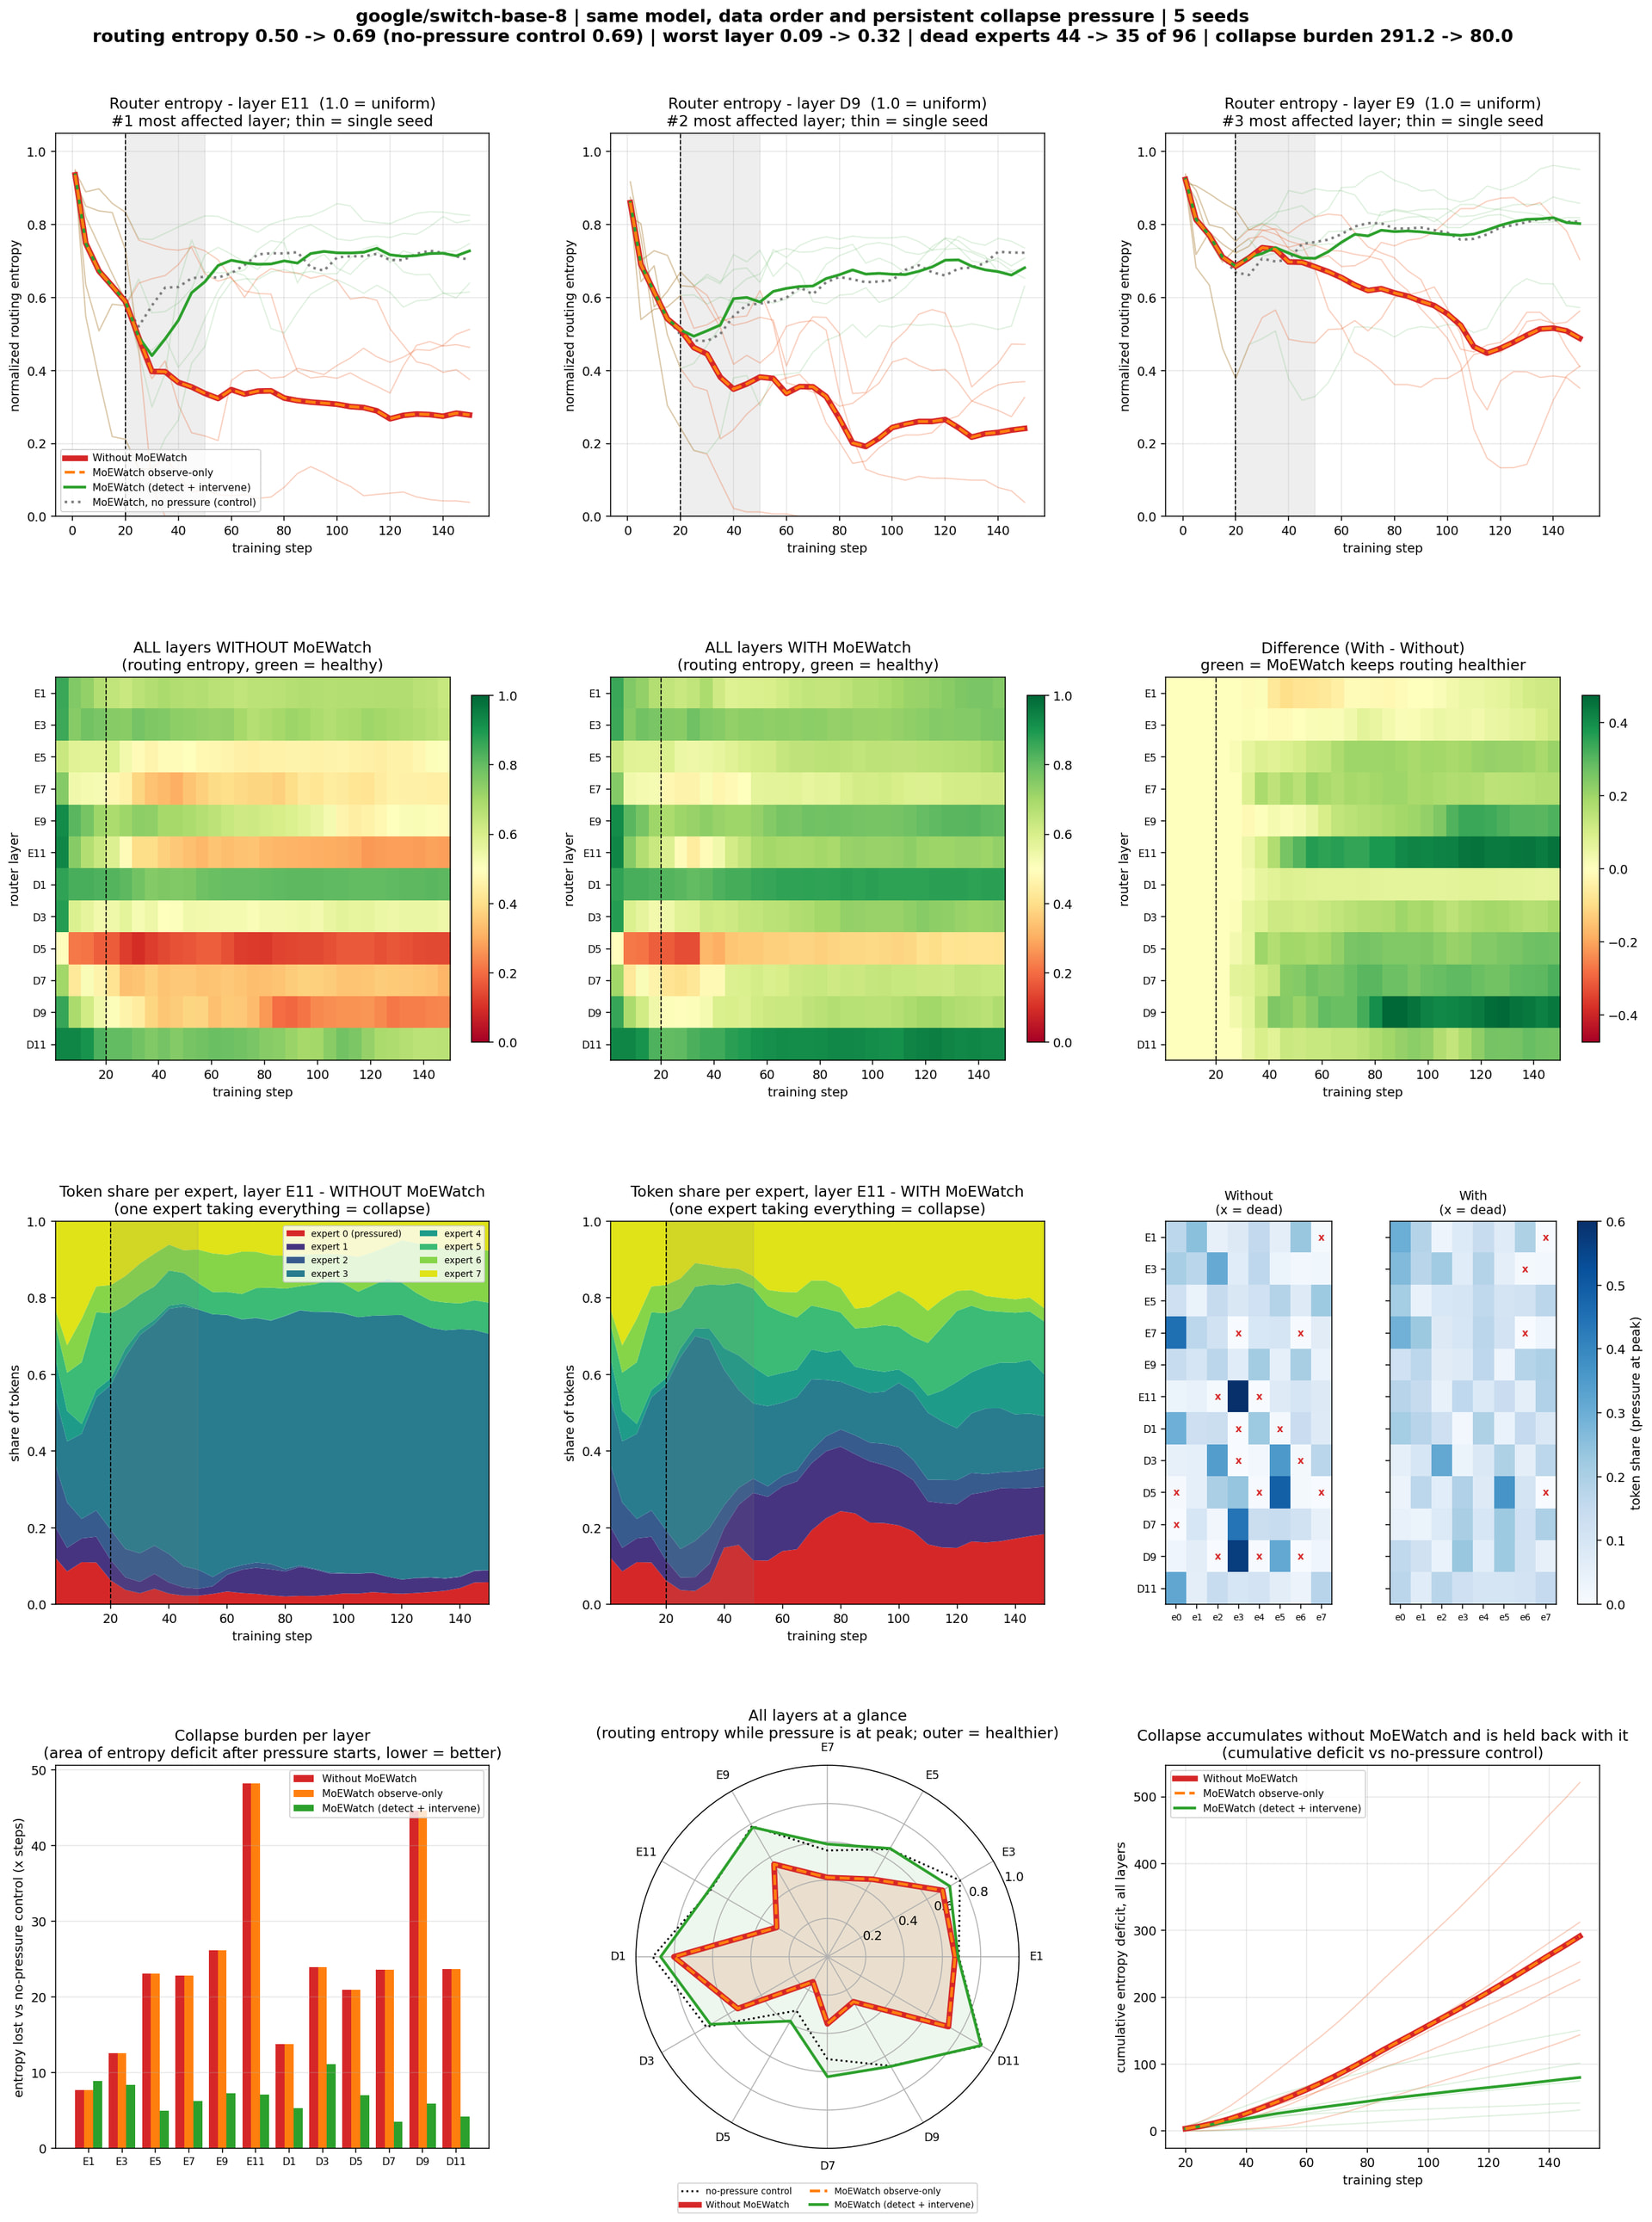
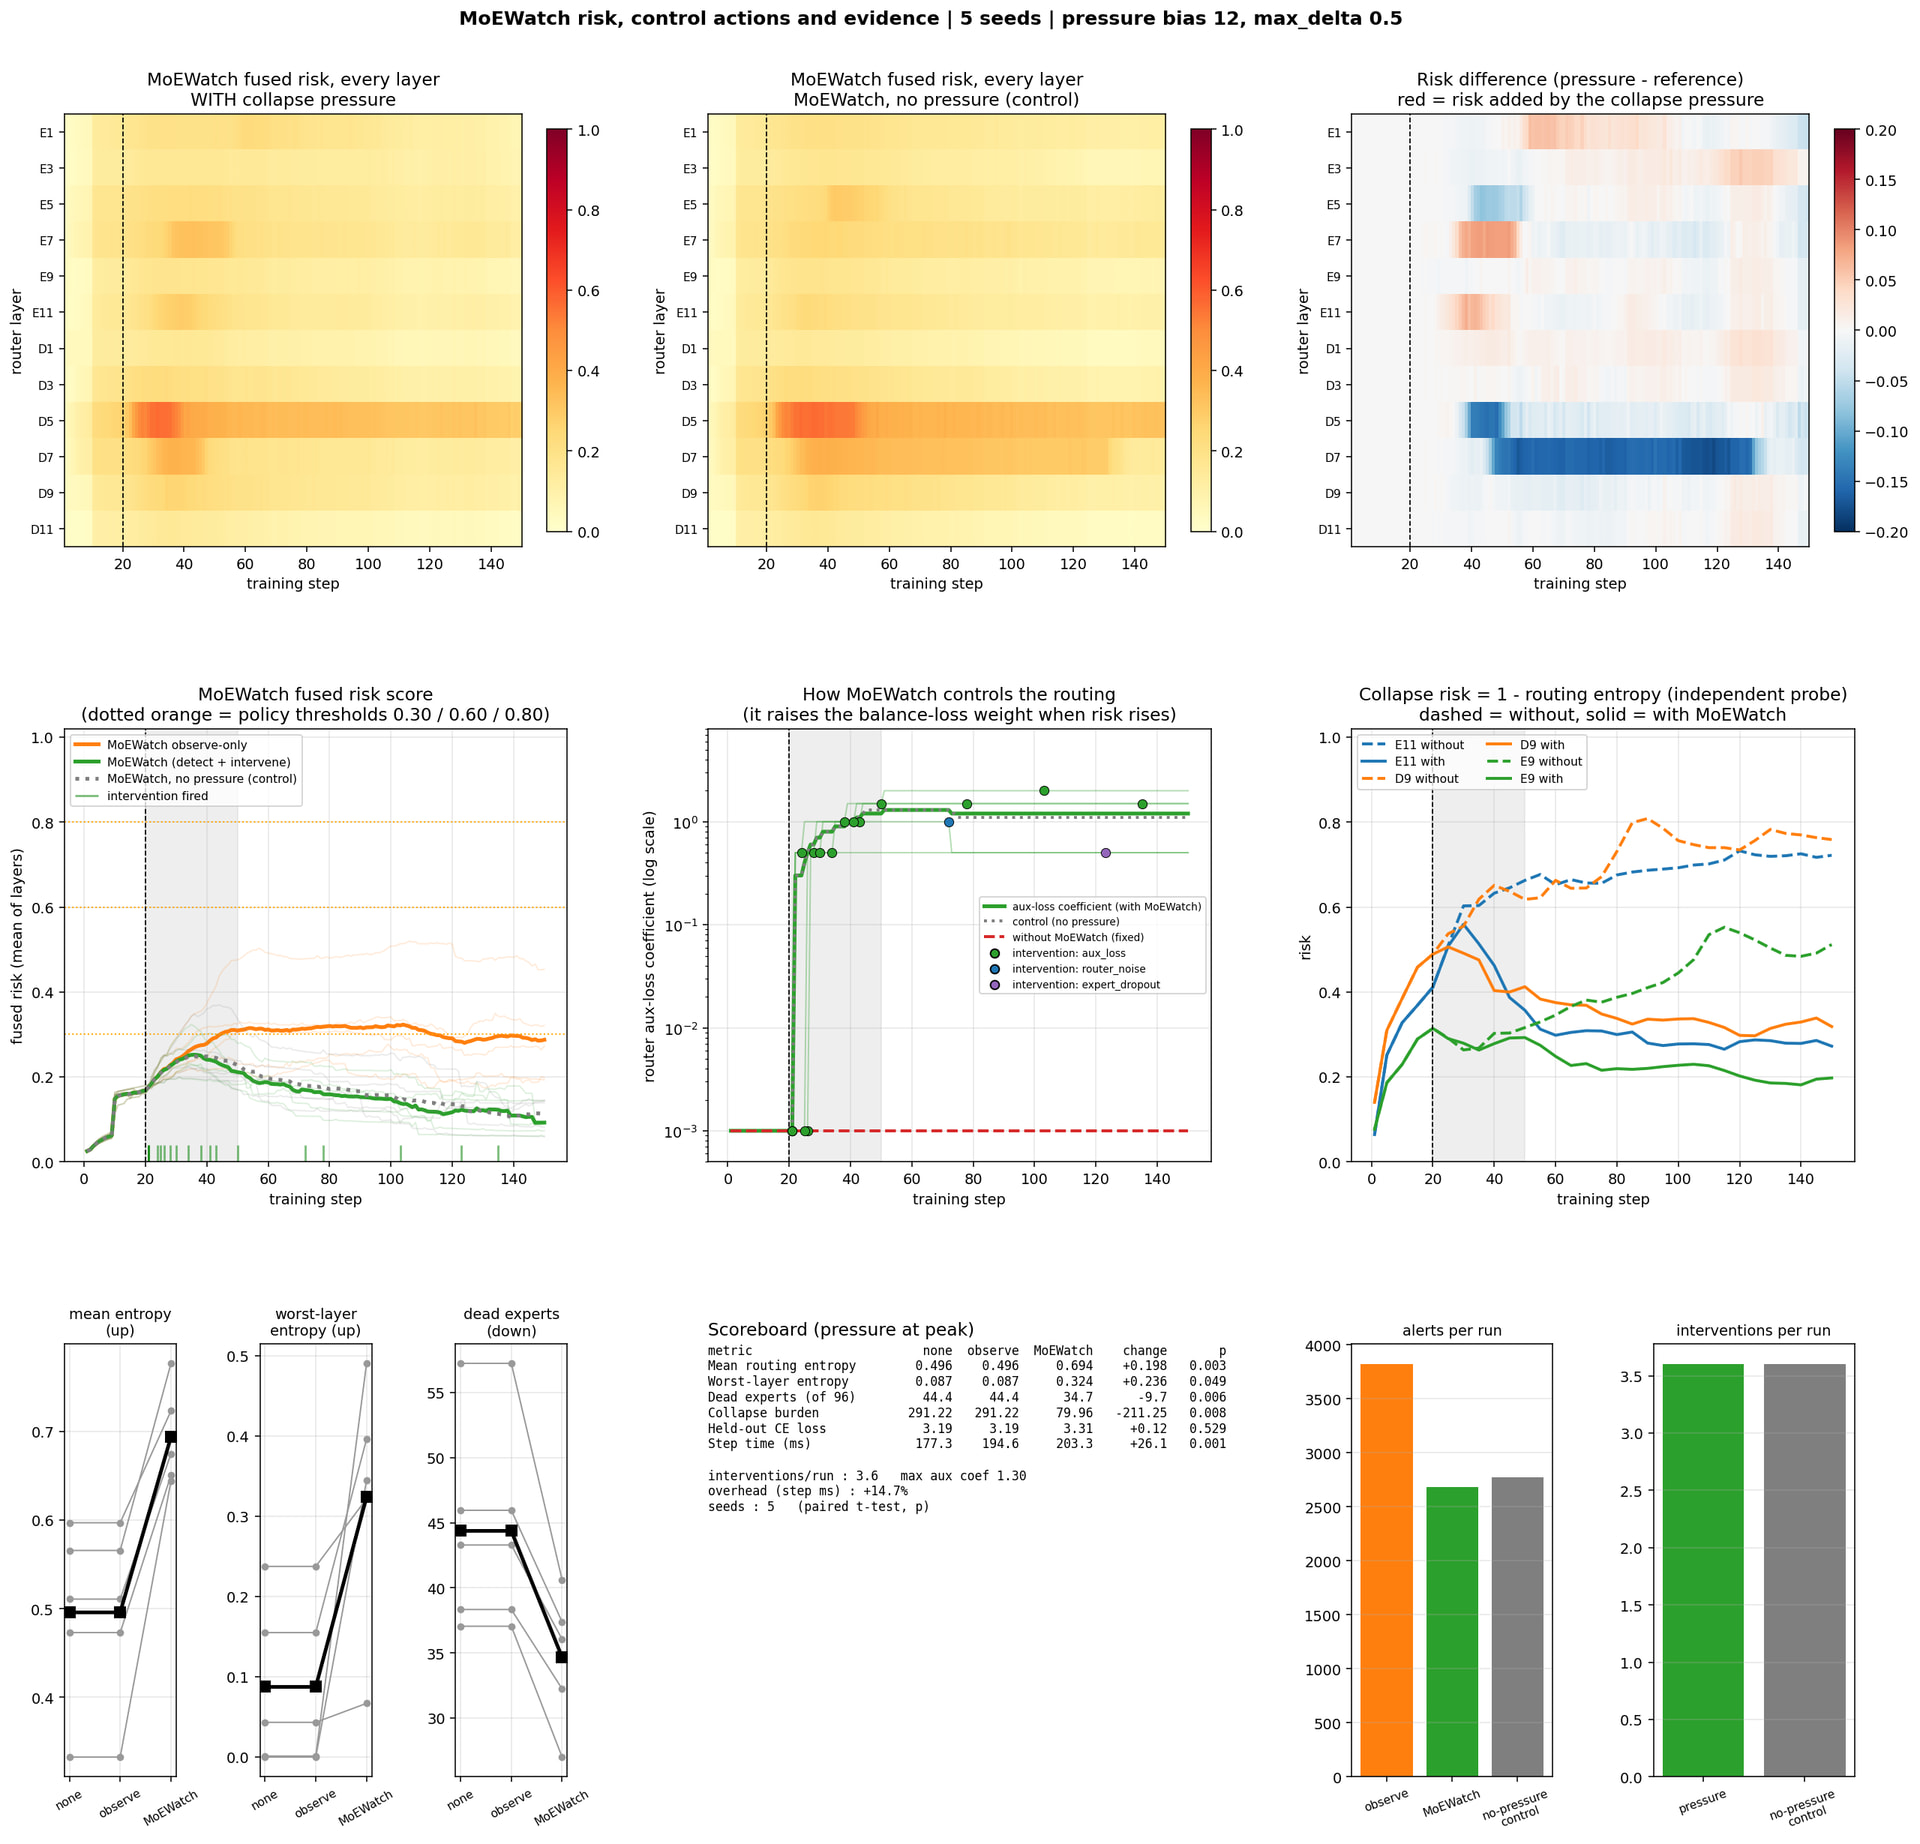
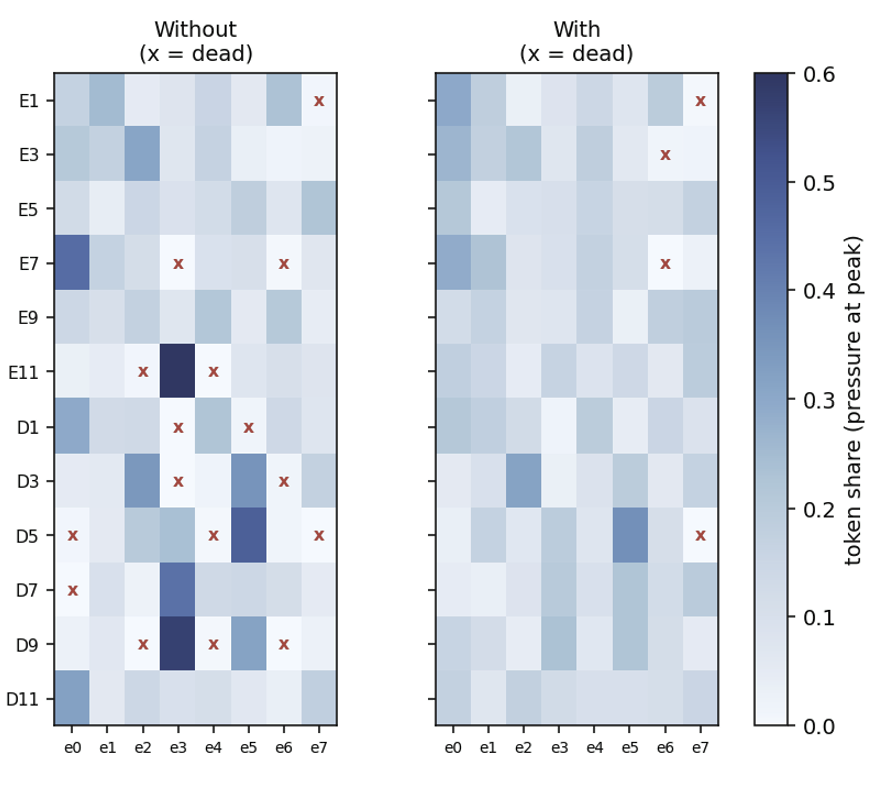
Google Switch-base-8 Results
Same model, same data order, and persistent collapse pressure across 5 seeds.
Without MoEWatch
Mean routing entropy: 0.50 → severe dropWorst layer entropy falls to 0.0944 dead experts out of 96High collapse burden (291.2)
With MoEWatch (detect + intervene)
Mean routing entropy rises to 0.69Worst layer recovers to 0.32Dead experts reduced to 35Collapse burden drops sharply to 80.0
Live interventions keep more experts alive and reduce overall collapse under the same pressure.
From Abineshabee  - Is now available on GitHub. It’s still experimental and under active benchmarking, but you’re welcome to try it with
pip install -e . and share your feedback as development continues.